Model overview · Mixtral
Mixtral 8x7B
Generated from Architecture IR 0.1.0 · revision de132a80b2
· report a correction
Overview
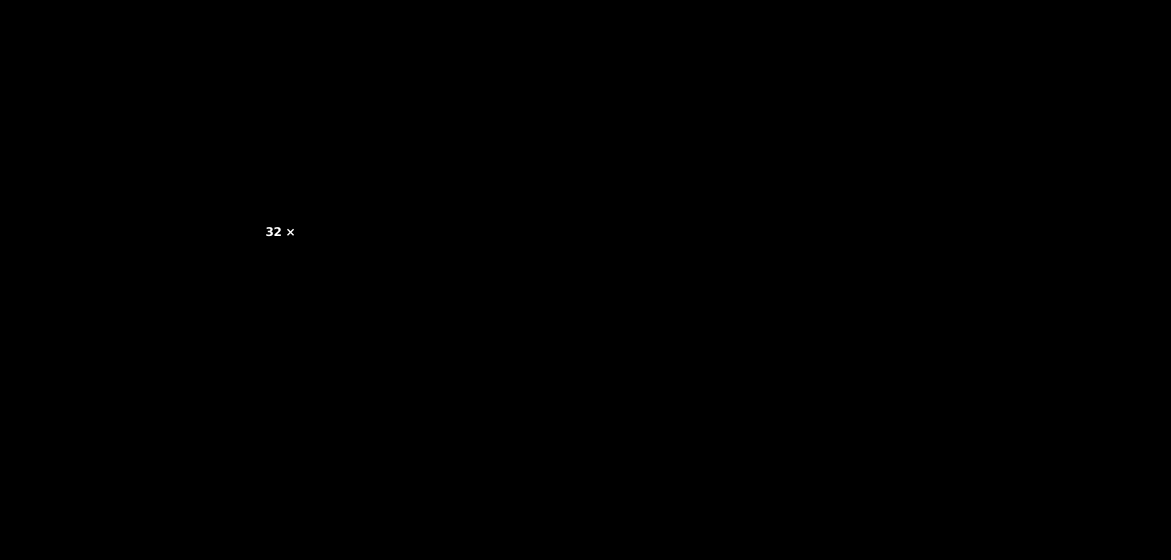
Fact sheet
- Layers
- 32
- Hidden size
- 4096
- Attention heads
- 32 · KV 8
- Vocab
- 32,000
- Context
- 32K
- Params
- 46.7B total / 12.9B active
Architecture Genome
One column per layer — top: attention, bottom: FFN/MoE.
Layer
attention (GQA/MLA) linear / recurrent attention MoE dense FFN
Evidence
Every visible number resolves to one of these claims. Inferred or unknown values are never shown as fact.
| Claim | Value | Status | Source |
|---|---|---|---|
facts.num_hidden_layers | 32 | • reported | hf_config · $.num_hidden_layers |
facts.hidden_size | 4096 | • reported | hf_config · $.hidden_size |
facts.num_attention_heads | 32 | • reported | hf_config · $.num_attention_heads |
facts.vocab_size | 32000 | • reported | hf_config · $.vocab_size |
facts.context_tokens | 32768 | • reported | hf_config · $.max_position_embeddings |
facts.total_params | 46700000000 | • reported | model_card · parameter count |
facts.num_key_value_heads | 8 | • reported | hf_config · $.num_key_value_heads |
topology.attention_groups[0] | "32 GQA layers" | • reported | hf_config · layers config / architecture table |
topology.experts.routed_total | 8 | • reported | hf_config · $.n_routed_experts |
topology.experts.active_routed | 2 | • reported | hf_config · $.num_experts_per_tok |
topology.experts.shared | 0 | • reported | hf_config · $.n_shared_experts |
topology.position_encoding.type | "rope" | • reported | hf_config · rope settings |
facts.active_params | 12900000000 | = derived | derived · dense or activated experts + attention params |
Compare
Compare this model with any other catalog model (see catalog).